TECH,- Amazon Web Services has added graphics processing unit support to AWS Lambda Managed Instances, allowing developers to run selected AI, video and scientific tasks through an event-driven service rather than manage their own GPU servers. The 18 November announcement targets organisations that want the power of specialised computing hardware without building an entire operating layer around it. Its value will depend on workload patterns, cost and how much control teams need over the underlying machines.
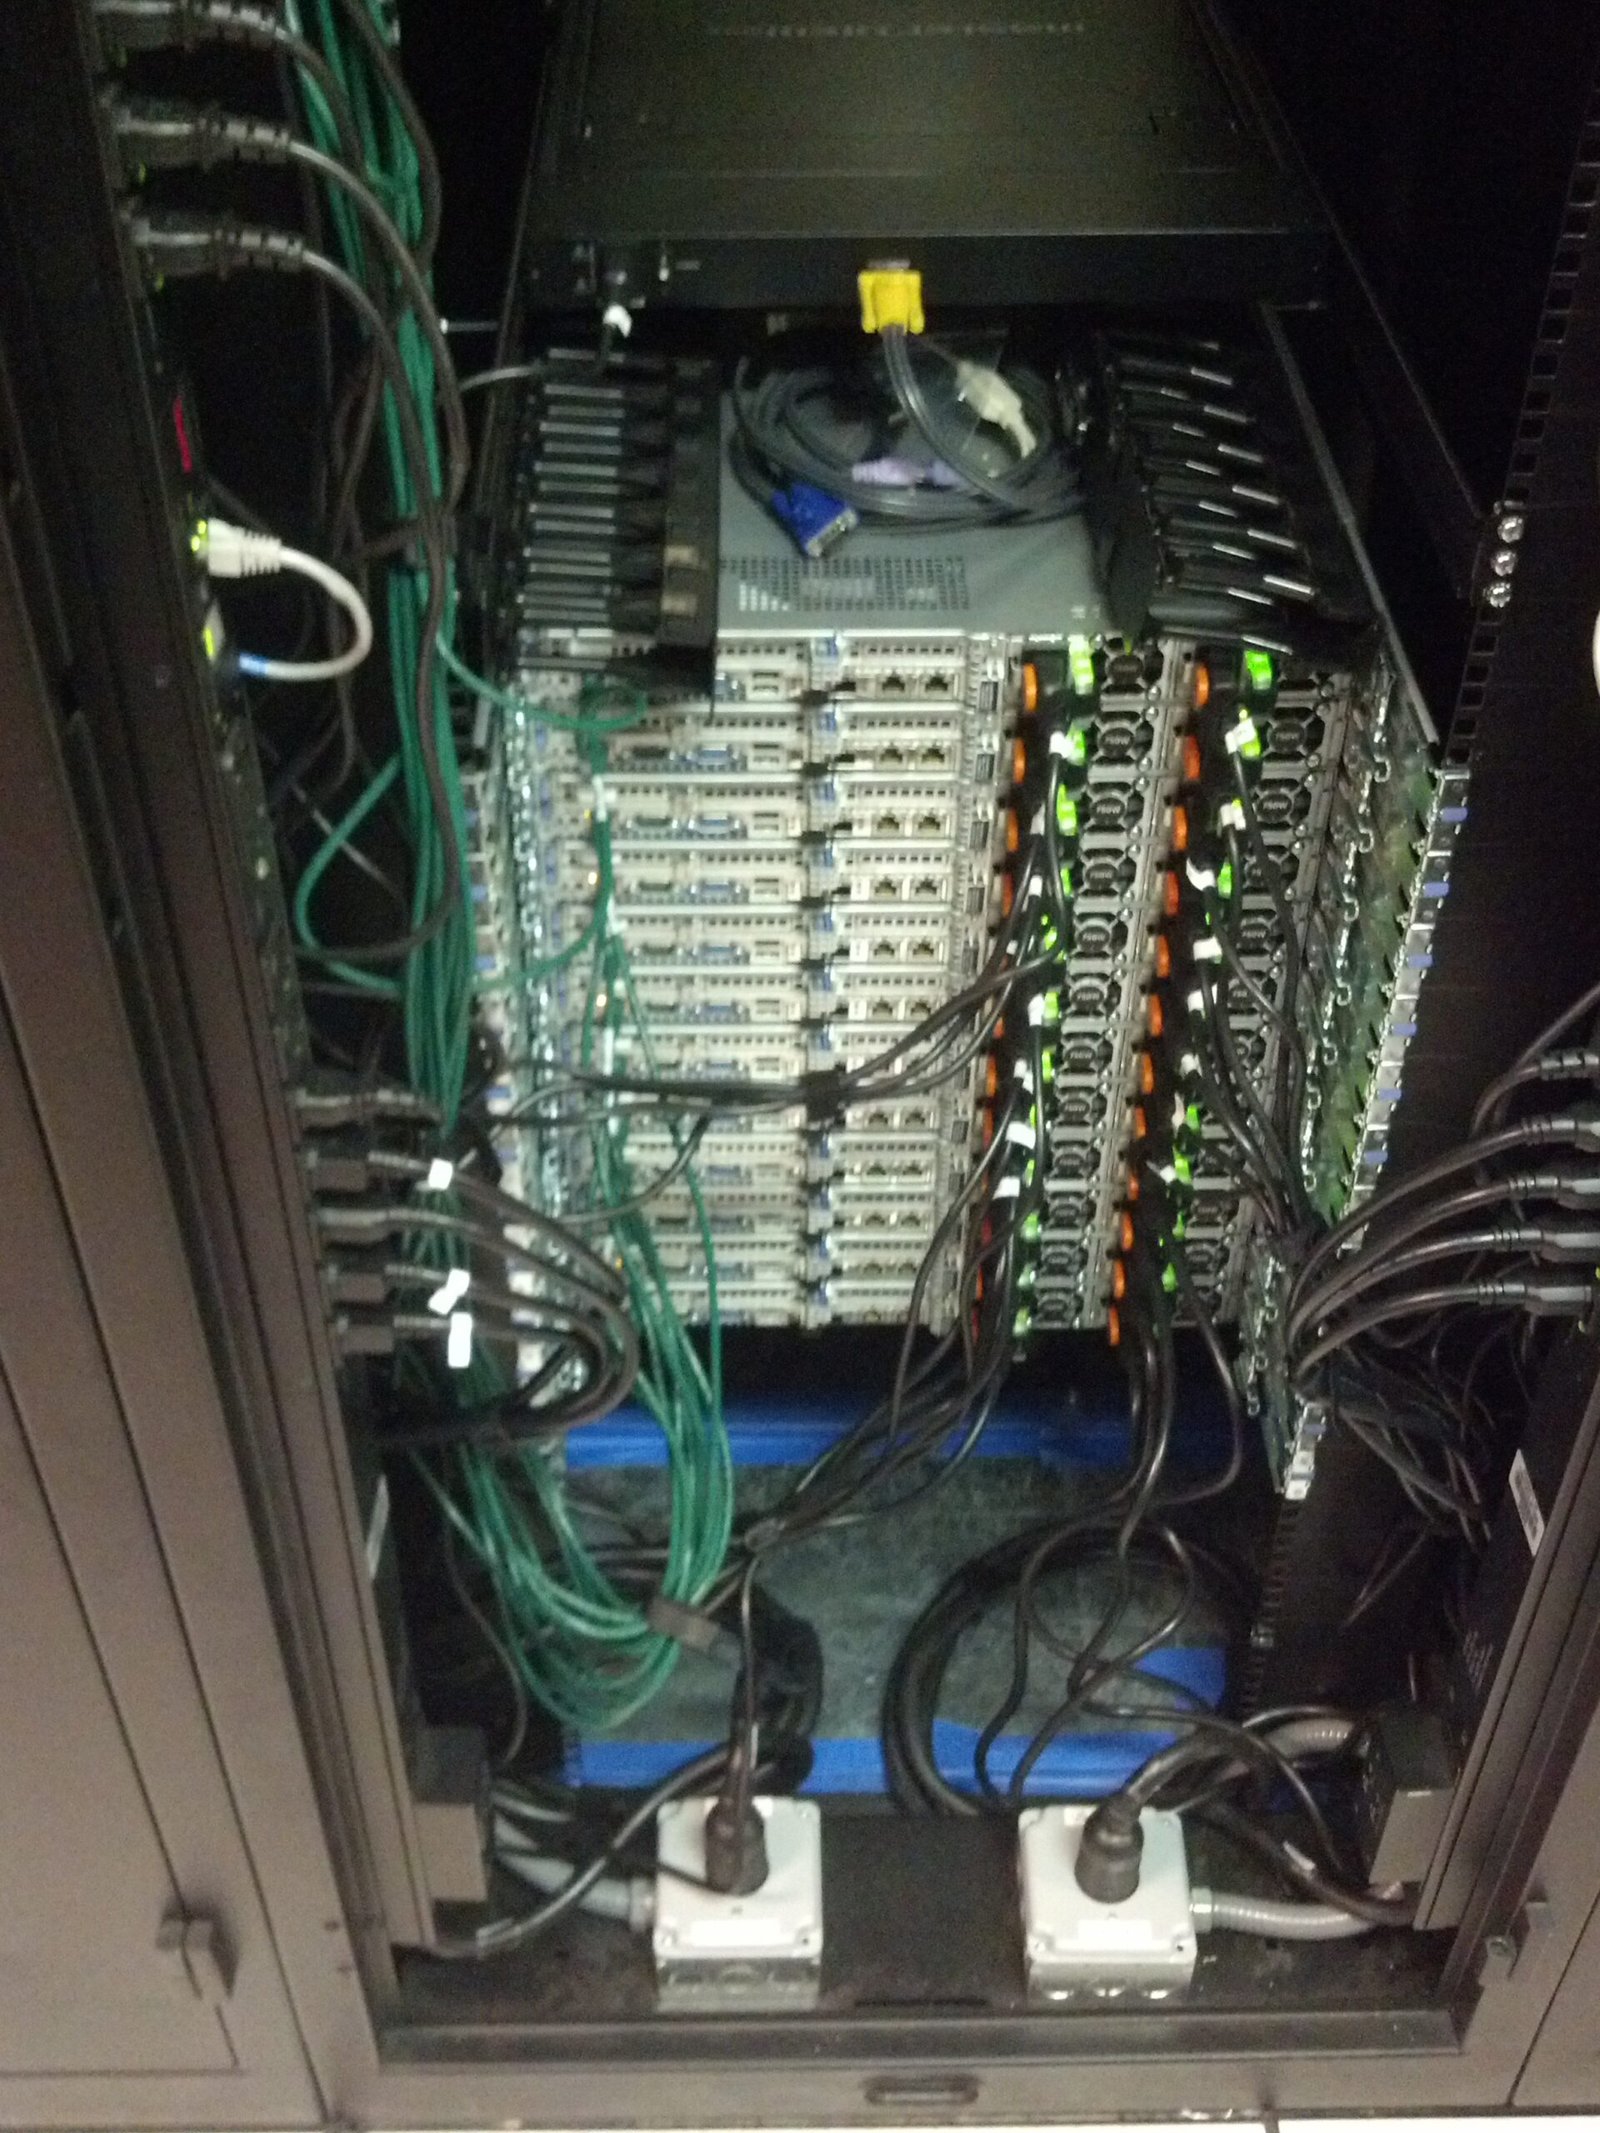
AWS Lambda is commonly used to run short pieces of code when an event occurs, such as a file being uploaded or a service receiving a request. GPUs are processors well suited to handling many calculations simultaneously, making them useful for AI model inference, video rendering and some scientific workloads. Bringing the two together can simplify the infrastructure needed to run specialised tasks.
How the new option works
The feature supports EC2 G-series graphics instances through Lambda Managed Instances. Developers package their application and dependencies into a container image, configure a capacity provider and connect the function to events. AWS takes responsibility for much of the provisioning and scaling. It also supplies base images that contain commonly used frameworks, including PyTorch and tools for serving AI models.
This reduces the need for developers to configure drivers, operating-system images and cluster components themselves. A media company, for example, might want to process uploaded videos automatically, while a software team might trigger a model to analyse documents after they arrive in cloud storage. These examples show possible uses; they are not claims that AWS has measured equivalent results for every customer.
The service can run several invocations within one environment and adjust its use of capacity based on demand. It integrates with more than 200 event sources, according to AWS. But serverless does not mean hardware disappears. GPU resources must still be provisioned somewhere, and sustained workloads may have different economics from occasional tasks.
What enterprises will pay
AWS says customers pay the applicable EC2 On-Demand instance charge, a 9.75 per cent Lambda management fee and US$0.20 per million requests. Savings Plans and Reserved Instances may apply to the underlying compute. The exact cost of a job also depends on instance type, duration, utilisation and related storage or network charges.
This distinction matters because serverless computing is often marketed as paying only for use. Under a managed-instance model, firms should examine how capacity is allocated, idle time and the minimum resources needed. A predictable, continuously busy AI service may be cheaper on carefully managed dedicated infrastructure, while fluctuating event-based work may benefit from reduced administration.
Why availability and governance still matter
The feature is available in AWS commercial regions that support both Lambda Managed Instances and the relevant G-series hardware. Businesses should verify availability in their chosen region and examine data-residency requirements before deployment. A company in Singapore cannot assume every capability operates identically in all markets.
AI workloads also introduce model licensing, information security and monitoring challenges. The managed service may reduce infrastructure tasks, but customers remain responsible for application logic, access permissions, sensitive data and the quality of generated outputs. Serverless architecture does not remove the need for observability or incident response.
For enterprises in ASEAN, the announcement illustrates a broader trend towards making advanced computing accessible to teams without dedicated hardware specialists. The real test will be whether simplified deployment improves time to market and whether detailed costs remain attractive at production scale. Developers should pilot a representative workload, measure end-to-end performance and compare it with alternative architectures before committing.